Overview
The second NLP project from my Personifwy internship: a supervised classifier for detecting hate speech in text.
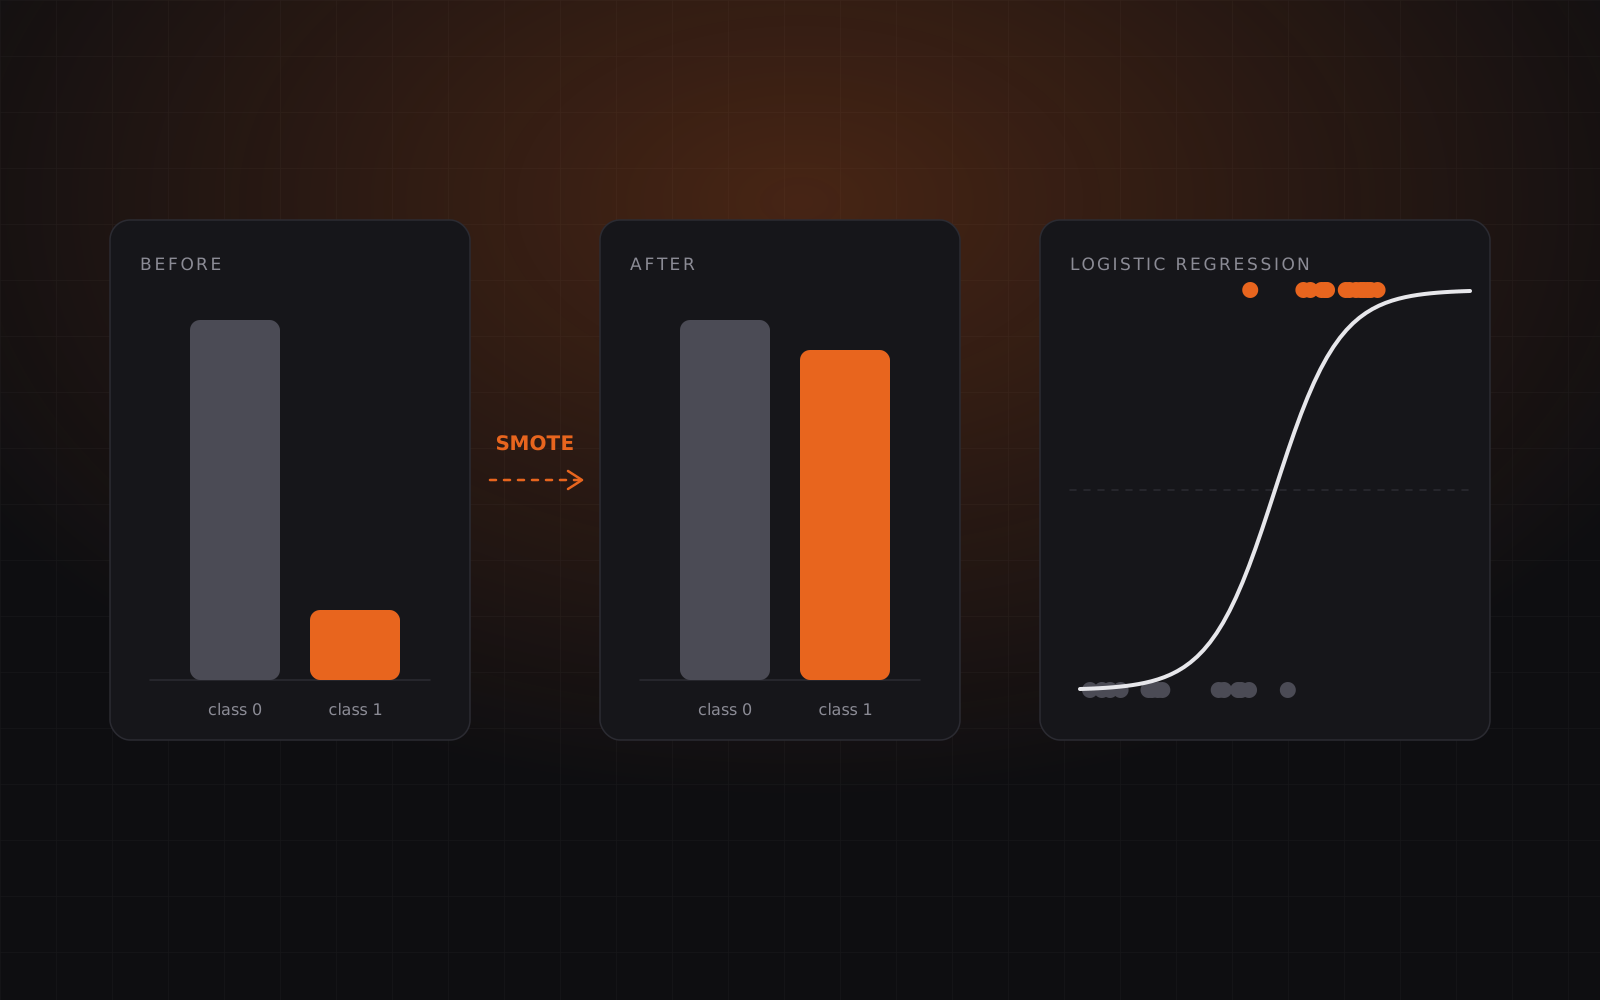
The central challenge was class imbalance, which I addressed with SMOTE before training. The model reached a reported 92% classification accuracy.
The problem
Hate-speech detection is a text-classification task with two complications: the language is highly contextual, and hateful examples are usually a minority of the data. A model trained naïvely on imbalanced data can look accurate while rarely identifying the class that matters most.
Pipeline
Balancing the classes before training was the key step.
5 layers · select a layer for details
-
Input Labelled text
Text samples labelled for hate speech, with the hateful class in the minority.
-
Preprocess NLP preprocessing
Cleaning and normalizing text before feature extraction.
- Python
-
Balance SMOTE oversampling
Synthetic minority-class examples reduce the imbalance the model sees during training.
- SMOTE
-
Model Logistic Regression
An interpretable linear classifier.
- scikit-learn
- Logistic Regression
-
Output Predicted class
Evaluated with classification accuracy.
Approach
Preprocessing
Text was cleaned and normalized with standard NLP preprocessing before being converted into numeric features.
Handling class imbalance with SMOTE
SMOTE (Synthetic Minority Over-sampling Technique) creates synthetic examples of the minority class by interpolating between existing examples in feature space. Balancing the classes gives the classifier more minority-class examples to learn from, instead of letting the majority class dominate training.
Logistic Regression
Logistic Regression is a linear model that estimates the probability that a piece of text belongs to a class. It is fast, well understood, and its coefficients are interpretable — useful for inspecting which terms drive a prediction.
Results
The model achieved a reported 92% classification accuracy.
Limitations
- Accuracy can mislead on imbalanced data. Per-class precision, recall, and F1 score say much more about how well the minority class is detected.
- Oversampling needs care. SMOTE should be applied only to training data (within each cross-validation fold) so that evaluation reflects real, unseen examples — something I'd make explicit in any follow-up write-up.
- Context is hard. Sarcasm, reclaimed terms, and coded language are difficult for bag-of-words style models. This project is a study in text classification, not a content-moderation system, and its performance depends on the dataset and its labelling guidelines.